Solutions · AI Infrastructure
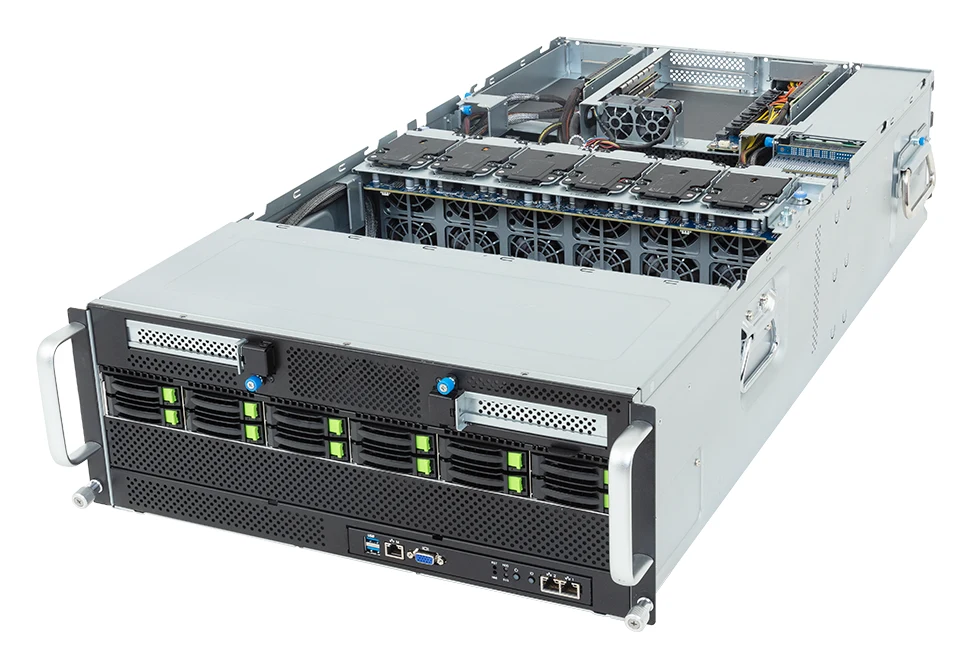
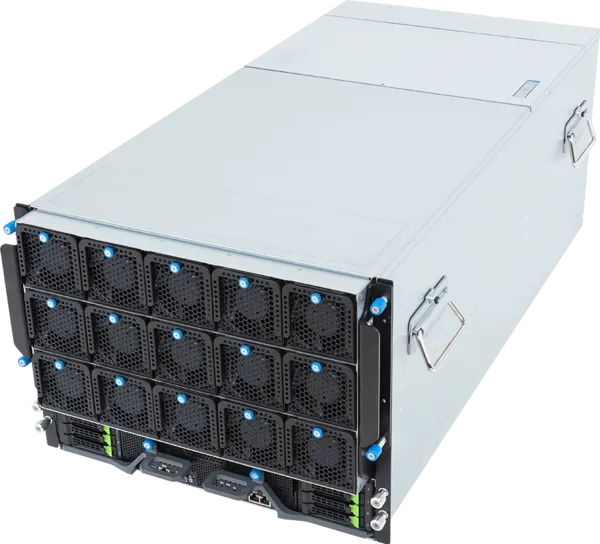
Gigabyte 4U and 8U platforms with up to 8 or 10 GPUs, designed for LLM training, real-time inference, computer vision and heavy machine learning pipelines.
Up to 8 or 10 GPUsHGX H100 · H200 · B200NVLink · NVSwitch400G / 800G networking3000 W+ PSUs
Market landscape
Larger models need more GPUs working together. The bottleneck moves from the chip to the interconnect, the network and rack power.
Training and fine-tuning LLMs requires several high-performance GPUs in the same server, with enough memory for the model.
Without a dedicated interconnect, GPUs spend more time exchanging data than computing.
AI clusters rely on 400G to 800G networking to scale training across servers.
8-GPU servers require high-power PSUs and cooling sized for continuous load.
Engineering highlights
Acceleration
Support for up to 8 or 10 dual-slot GPUs per server.
Platform
PCIe architectures and NVIDIA HGX H100, H200 and B200 baseboards.
Interconnect
High-speed communication between GPUs in the same server.
Networking
Dedicated network topologies for AI clustering.
Power
High-power redundant PSUs to keep every GPU under load.
Form factor
Large chassis for GPU density and airflow.
Recommended hardware
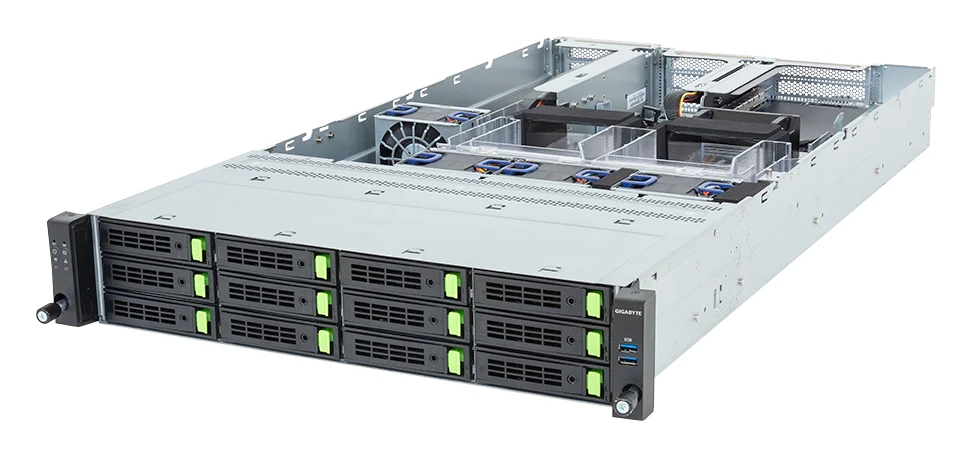
A line of large GPU-accelerated servers in 4U and 8U.
For channels and resellers
Strategic partnership with Giga Computing and access to Gigabyte GPU-accelerated platforms.
Technical support for sizing: GPUs, interconnect, cluster networking, power and cooling.
Stock availability and invoicing through the distributor to speed up the reseller's project closing.
Project quote
Describe your scenario and a technical specialist will get back to you with the recommended configuration.